Design Multimodal Embeddings architecture for a coding copilot for a large engineering org
Senior architecture interview question on Multimodal Embeddings within Embeddings.
Read full explanationSep 30, 2026: Cohere Embed 5 Pro and Fast share one embedding space—index with Pro, query with Fast (same dimension)—for cheaper RAG without a re-index
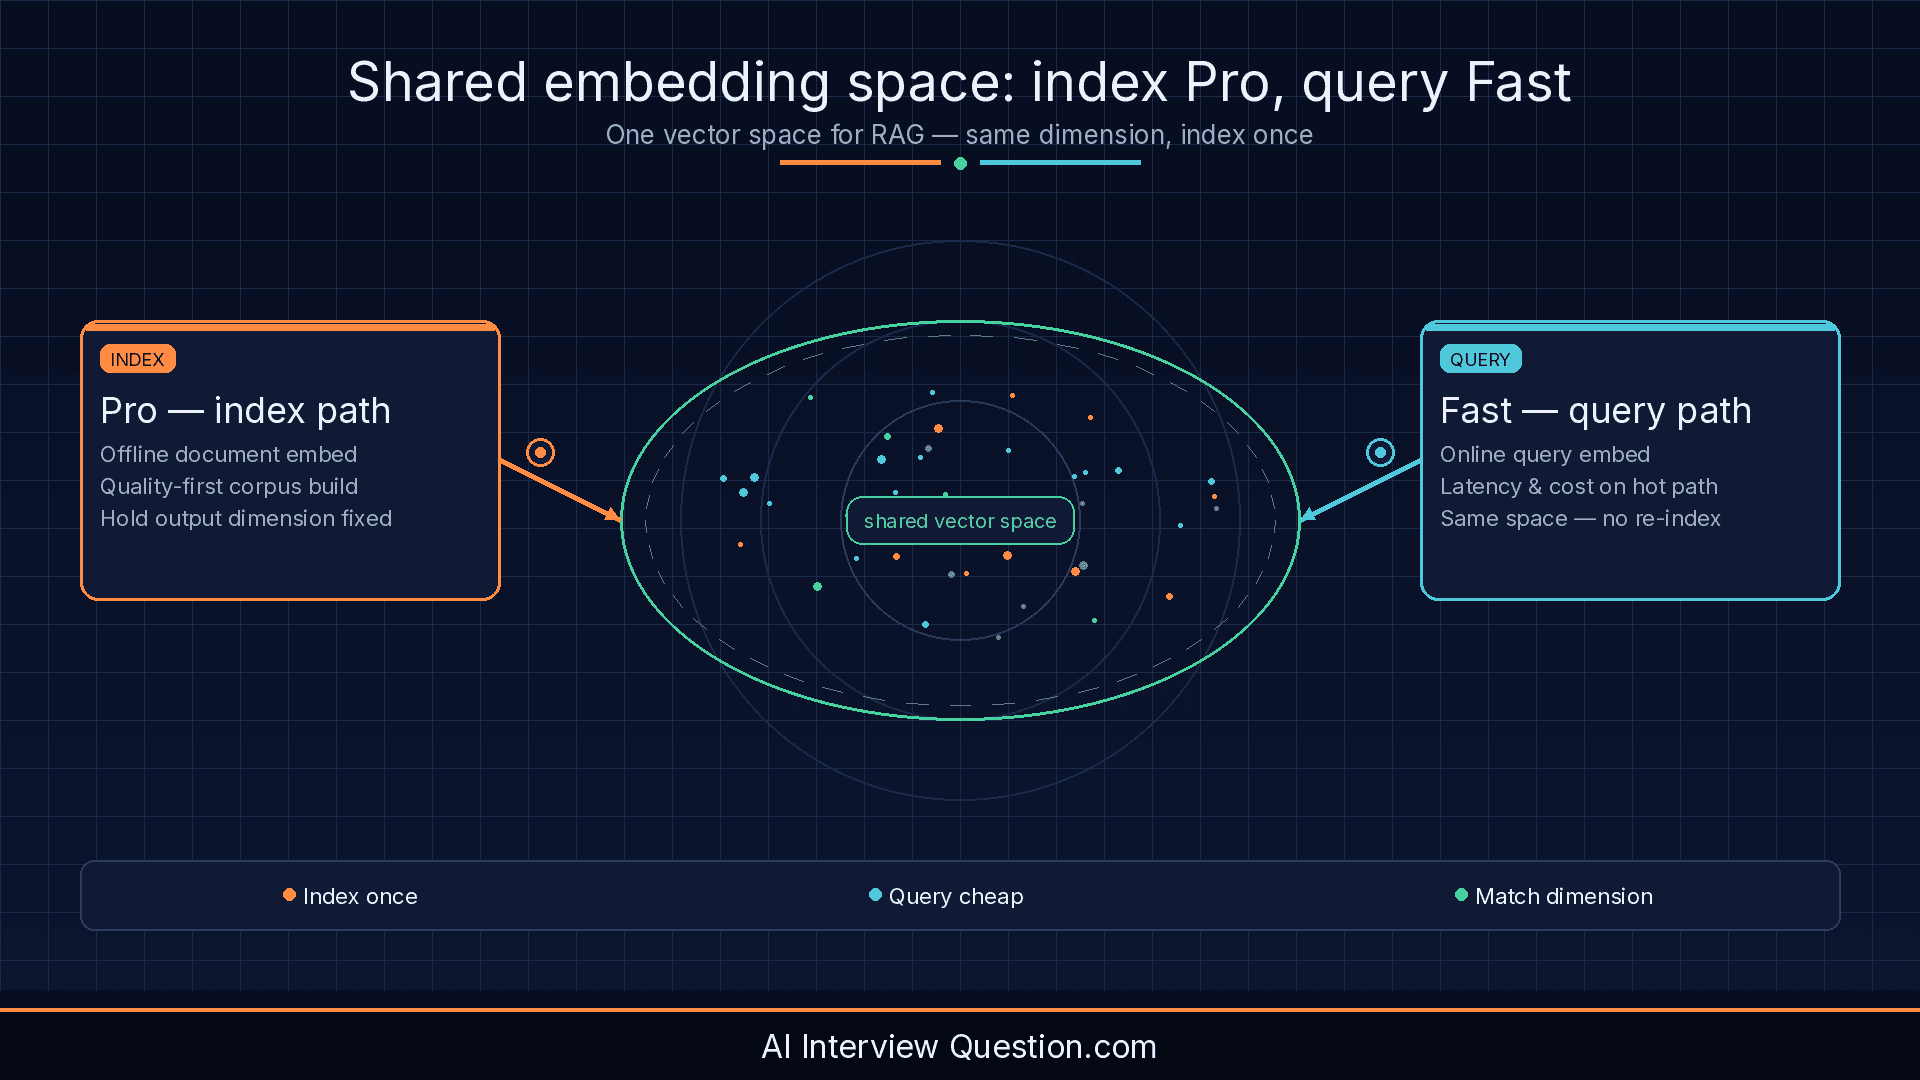
On September 30, 2026, Cohere announced Embed 5 as a Pro and Fast pair for enterprise retrieval, RAG, and agentic search. For interview prep, the useful story is practical: a normal embedding upgrade often forces a full re-index, but Cohere says these two tiers share one embedding space, so you can index documents with Pro and query with Fast without rebuilding the index—if both sides use the same output dimension.
That shared-space claim is the interview hook. Cohere’s recommended pattern for many customers is index offline with Pro for quality, then query online with Fast for latency and cost. Official Embed docs list the model IDs as embed-v5.0-pro (“most capable… higher quality than Fast, at higher latency”) and embed-v5.0-fast (“faster, lighter version”). Both are multimodal (text, images, or fused text plus image), support 100+ languages, offer a 128K-token context window, and expose Matryoshka output dimensions of 2048, 1536, 1024, 768, 512, and 256, with float, int8, and binary formats. Self-hosting is supported; the announcement also mentions private deploy via vLLM.
Embed 5 is generally available on the Cohere API and Model Vault, Microsoft Foundry, and Amazon SageMaker. Sample code uses model="embed-v5.0-pro" with input_type search_document or search_query. List pricing Cohere published on the announcement: text at $0.12 per 1M tokens for Pro and $0.08 per 1M tokens for Fast; image inputs at $0.40 per 1M tokens for both tiers.
Cohere-reported performance figures belong in the interview answer only with attribution. On ViDoRe V3 (parsed text, RCP-nDCG@10), Cohere reports Embed 5 Pro averaging 85.8 (+8.8 versus Embed 4), ahead of Voyage 4 Large (83.7), Gemini Embedding 2 (83.2), and OpenAI text-embedding-3-large (75.5) in the comparison set Cohere shows; Fast averages 84.5. Treat those as vendor evals under Cohere’s methodology—footnote language on the blog notes RCP-nDCG@10 reflects a two-stage or reorder-style setup, not pure first-stage recall—and not as independent third-party proof or production SLOs. For throughput, Cohere reports Fast delivers an average of 2.4× higher document throughput than Pro across tested context sizes. On cross-model retrieval, Cohere’s normalized table on 40 development datasets puts Pro+Pro at 100 and Corpus Pro + Query Fast at 98.4 mean nDCG@10—close, but still a Cohere measurement on Cohere’s sets.
In an AI/ML interview, lead with the adoption pattern: keep identical output_dimension (and compatible Matryoshka or int8 settings) so Pro-indexed vectors stay comparable to Fast queries; contrast that with a vendor swap or dimension change that forces a rebuild. Say when you would still re-embed—leaving the shared space, changing dimension, or moving vendors. Validate on your own corpus evals rather than repeating only vendor tables. Discuss Matryoshka and int8 or binary compression as storage-versus-recall levers before a reranker. Pricing and the Pro-versus-Fast latency trade-off give you a clean cost story for agent hot paths without inventing customer counts or treating Compass Cloud as generally available (the announcement lists Compass Cloud as private beta).
Caveats keep the answer honest. Shared-space interchangeability requires the same output dimension. Leaderboard wins are Cohere-reported on Cohere’s comparison set, not a universal industry proof. This post is product news about Embed 5 Pro and Fast; it is not a substitute for a general embedding-selection guide. For interview day, the strong line is: index once with Pro for multimodal enterprise corpora, query cheap with Fast, hold dimension fixed, and prove quality on your evals before you trust the vendor chart.
https://cohere.com/blog/embed-5 https://docs.cohere.com/docs/cohere-embed https://cohere.com/embed
Deep explanations with architecture diagrams for every question below.
Senior architecture interview question on Multimodal Embeddings within Embeddings.
Read full explanationMid-Level scenario interview question on Embedding Dimensions within Embeddings.
Read full explanationSenior scenario interview question on Embedding Versioning within Embeddings.
Read full explanationSenior trade-off interview question on Multimodal Embeddings within Embeddings.
Read full explanationJunior scenario interview question on Text Embeddings within Embeddings.
Read full explanationJunior conceptual interview question on Cosine Similarity within Embeddings.
Read full explanationMid-Level conceptual interview question on Embedding Drift within Embeddings.
Read full explanationSenior conceptual interview question on Embedding Evaluation within Embeddings.
Read full explanation