Deep explanation
Debug Model Selection regression in a multi-tenant AI support platform
Senior debugging interview question on Model Selection within AI Career & Behavioral.
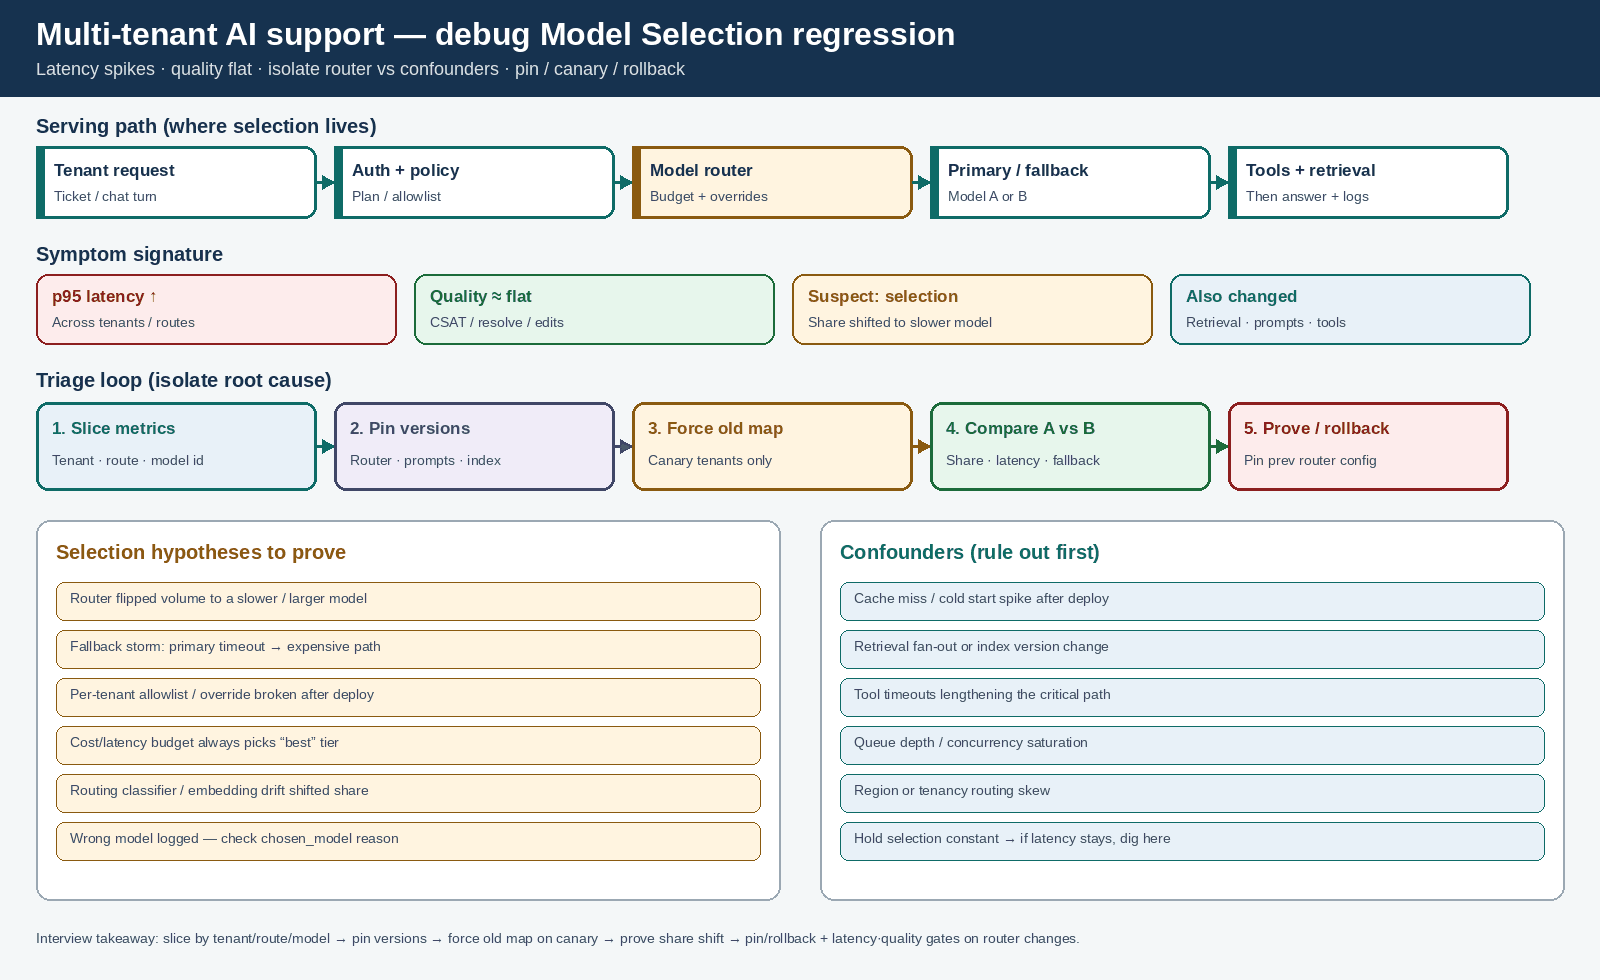
Quick answer
Confirm the symptom is real with sliced metrics: p95 latency up, quality flat, broken down by tenant, route, and selected model. Freeze what shipped in the same deploy—router config, model allowlists, prompt versions, retrieval index, and tool schemas—then pin versions so you can A/B against the previous router. Separate model selection from confounders like cache misses, cold starts, retrieval fan-out, tool timeouts, and queue depth. Compare traffic that landed on model A versus model B before and after the release, using canary or shadow tenants if available. Typical selection regressions: the router flipped traffic to a slower larger model, a fallback storm hit the expensive path, a per-tenant override broke, or a cost/latency budget mis-fire. Mitigate by pinning the previous router config, rolling back canaries, and adding joint latency-plus-quality gates on every router change.
The interview question
After a recent release, a multi-tenant AI support platform shows latency spikes while quality remains flat. Logs suggest the problem may involve Model Selection, but multiple subsystems changed in the same deploy. Walk through how you would isolate the root cause.
Deep explanation
Sign in to unlock the full answer
Free accounts include 5 full deep answers. Sign in to start unlocking.
- 30 more sections of deep explanation
- Real-world examples
- Common mistakes
- Interviewer expectations
- Follow-up questions