Deep explanation
Design Evaluation Strategy architecture for a coding copilot for a large engineering org
Senior architecture interview question on Evaluation Strategy within AI Career & Behavioral.
Quick answer
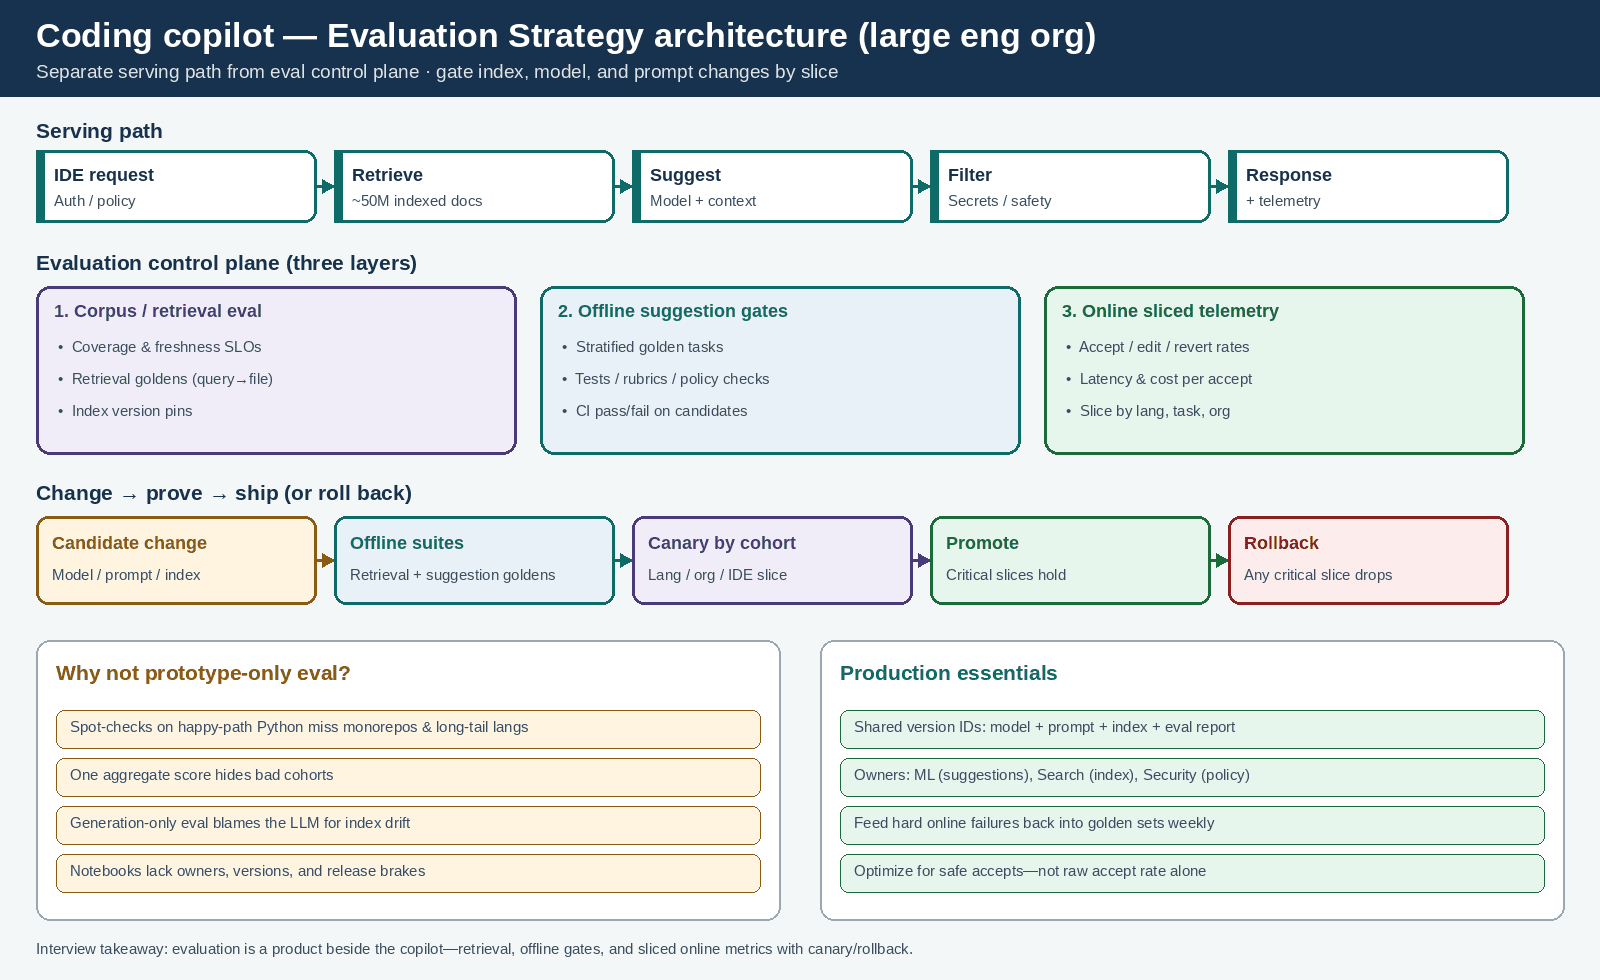
Treat evaluation as its own production service next to the coding copilot, not a one-off notebook. Split the stack into: (1) corpus/index eval for the ~50M indexed docs (freshness, coverage by language/repo, retrieval hit quality), (2) offline suggestion eval on versioned golden tasks (accept/edit/reject labels, unit-test pass where applicable), and (3) online telemetry (accept rate, edit distance, revert/undo, latency, cost) sliced by language, task type, and org. Gate model, prompt, and index changes with CI on golden sets, canary by cohort, and explicit rollback when any critical slice drops even if the global score looks fine. Prototype eval that only spot-checks happy-path Python will not scale; you need stratified fixtures, owners, and release brakes.
The interview question
a coding copilot for a large engineering org needs to scale Evaluation Strategy from a prototype to a production-grade AI Career & Behavioral capability serving 50 million indexed documents. What architecture would you propose, and why?
Deep explanation
Sign in to unlock the full answer
Free accounts include 5 full deep answers. Sign in to start unlocking.
- 40 more sections of deep explanation
- Real-world examples
- Common mistakes
- Interviewer expectations
- Follow-up questions