Deep explanation
Evaluate Scale Challenges quality in an AI search product
Senior evaluation interview question on Scale Challenges within AI Career & Behavioral.
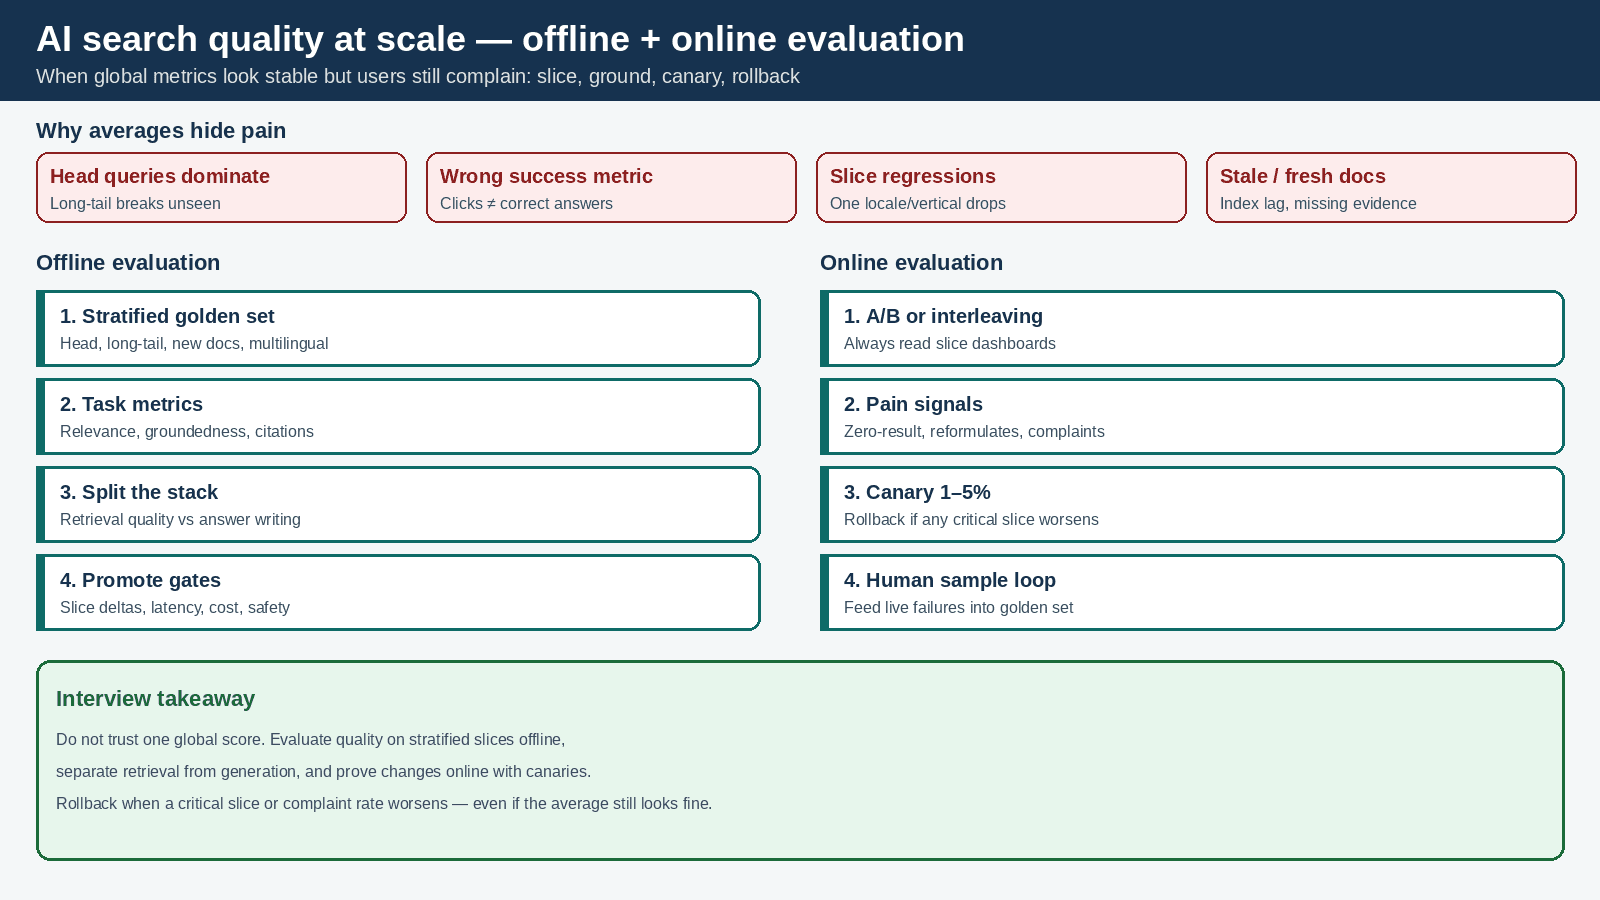
Quick answer
When aggregate metrics look fine but users still complain about an AI search product, treat it as a scale-and-slice problem: overall averages hide bad cohorts. Design offline eval with a stratified golden set (head queries, long-tail, new docs, multilingual, adversarial) scored on relevance, groundedness, and citation quality—not only click-through. Pair that with online eval: interleaved or A/B tests plus slice dashboards for latency, zero-result rate, and complaint rate by query class. Ship changes behind canaries with explicit rollback when any critical slice worsens even if the global score holds.
The interview question
an AI search product needs an evaluation strategy for Scale Challenges. Metrics look stable, but users still complain about quality. How would you design offline and online evaluation?
Deep explanation
What the question is really asking
Sign in to unlock the full answer
Free accounts include 5 full deep answers. Sign in to start unlocking.
- 21 more sections of deep explanation
- Real-world examples
- Common mistakes
- Interviewer expectations
- Follow-up questions